Windows · 297 MB installer
SimpleML
Click-and-play machine learning, on your own machine.
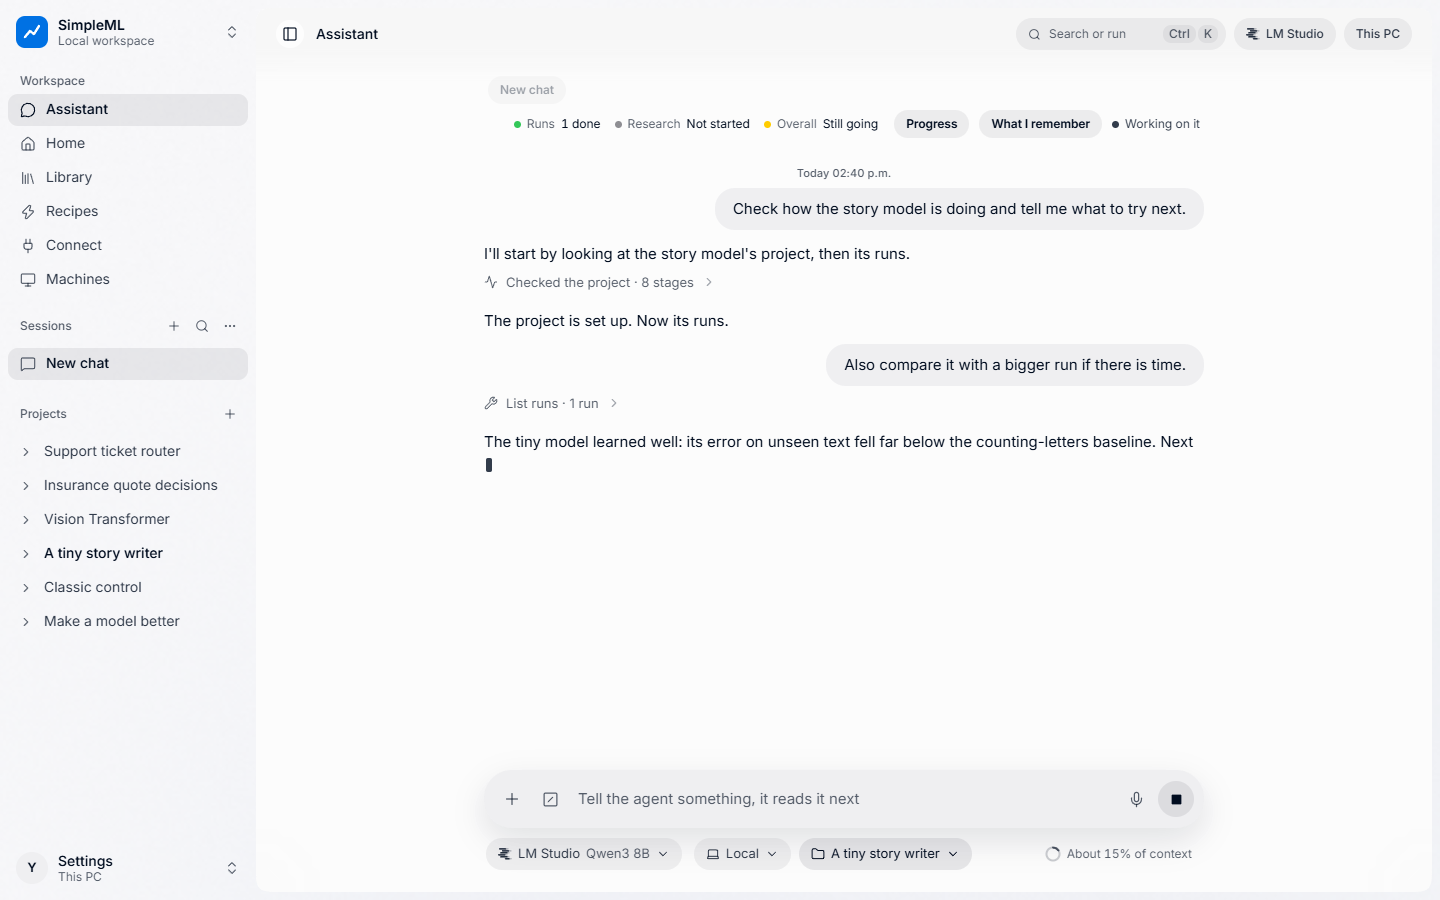
Inside the app
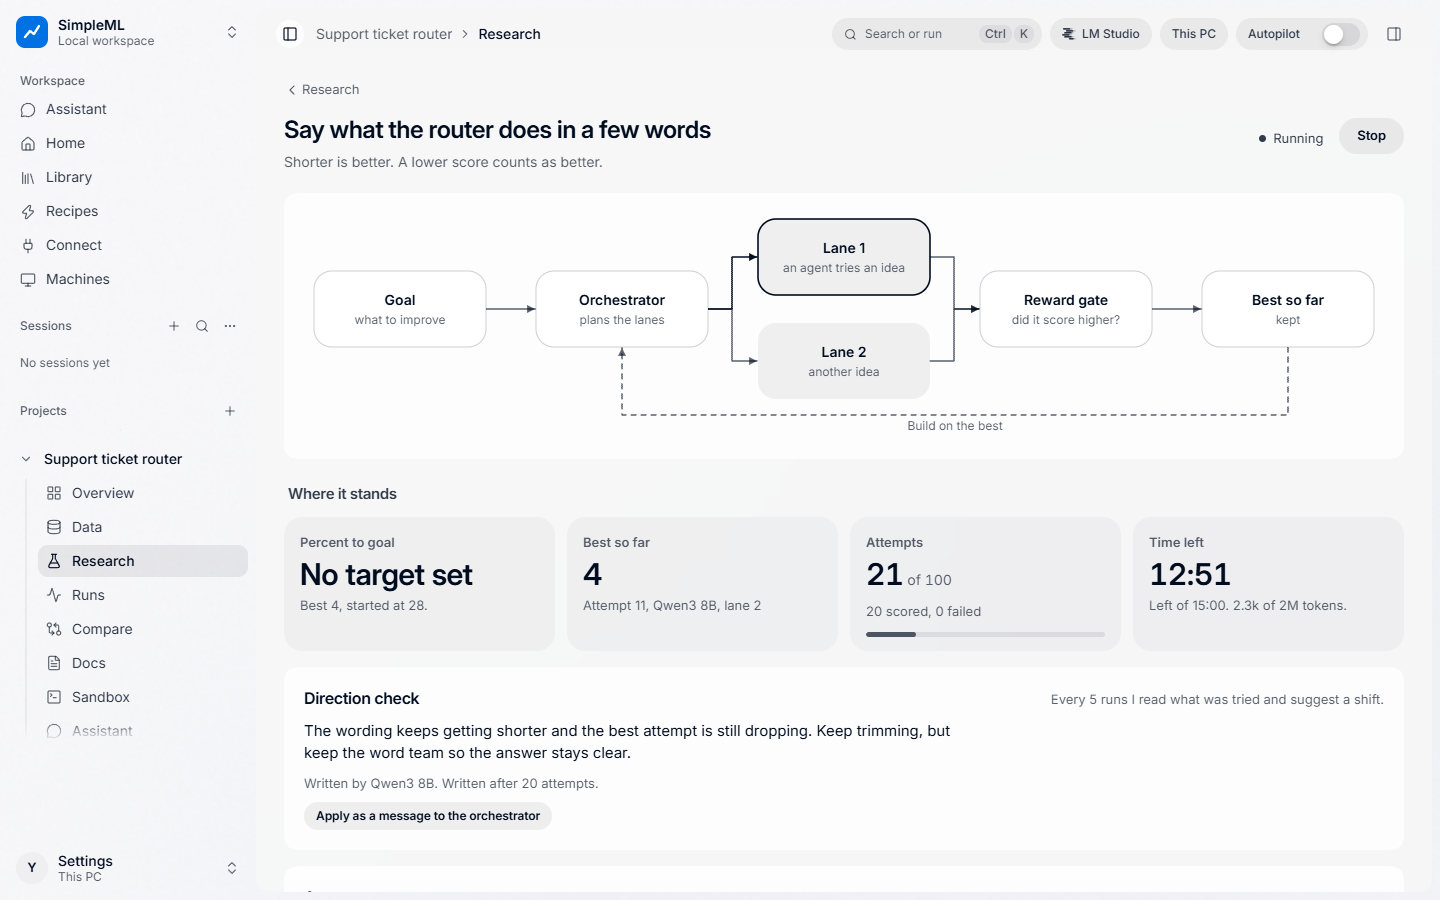
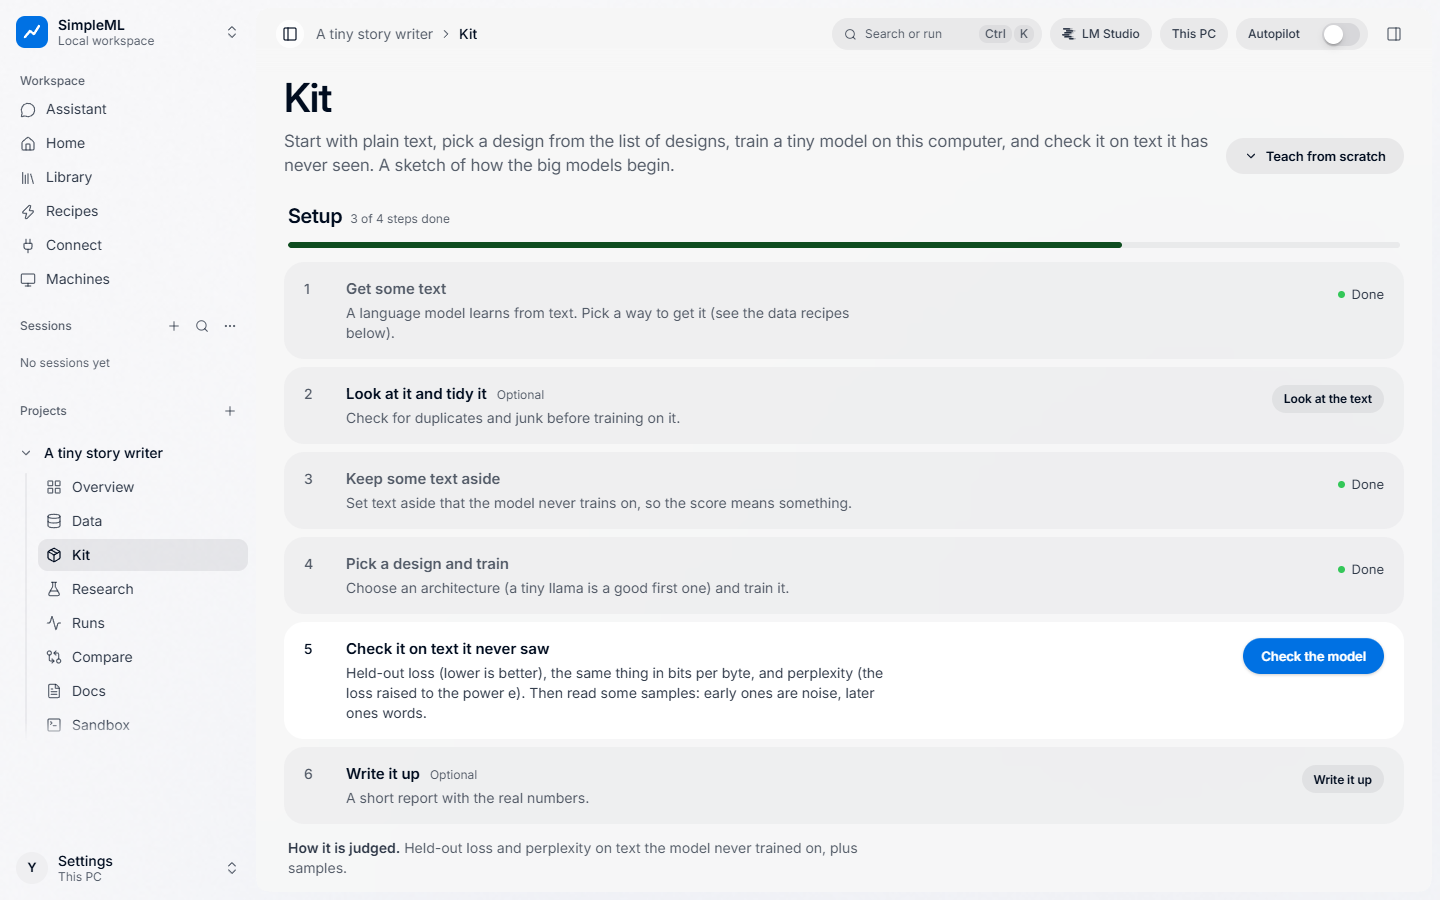
One app instead of a stack of tools
Doing ML usually means stitching together notebooks, data-prep scripts, training recipes and eval code, each with its own setup. SimpleML is one local desktop app: connect an agent, drop in your data or start from scratch, and it prepares the data, trains, evaluates and shows you the results.
How it works
Connect an agent, bring your data, and it prepares, trains, evaluates and shows the results.
01Connect
Connect an agent
Codex, Claude Code or a local model plans and runs the work.
02Data
Drop in data, or start from scratch
Bring your own files, or begin with nothing and let the agent set it up.
03Prepare
It prepares the data
The connected agent cleans and shapes the data for training.
04Train
Pre-training and post-training kits
Training runs from built-in kits, with research swarms for the open-ended search.
05Evaluate
Honest evaluation on sealed test rows
Test rows stay sealed during training, so the score you see is not inflated. The results are shown in the app.
Before and after
Measured on the previous app that SimpleML replaces: each change was tested on the tasks it was meant to fix and kept only if it beat the version before it.
Limits
The numbers on this page were measured on the previous app that SimpleML replaces, not on SimpleML itself. Ten runs a side is a small sample, and each fix tried alone did worse than the baseline; only the combination was kept.
Small ML tasks finished
Small ML tasks finished. Before 7 of 10, After 8 of 10. Higher is better.
10 runs per arm, small local model, Git Bash · 9 / 10 without Git · previous app. Source: lab/log.md, H-shell A5 and A6.
Failed shell commands per run
Failed shell commands per run. Before 2.0, After 0.0. Lower is better.
Same 10 runs · previous app. Source: lab/log.md, H-shell A5.
Time per run
Time per run. Before 119 s, After 85 s. Lower is better.
Same 10 runs · previous app. Source: lab/log.md, H-shell A5.
Tool router hits at 4 tools
Tool router hits at 4 tools. Before 101 of 140, After 132 of 140. Higher is better.
Of 140 steps, learned router vs BM25, p = 7.9e-9 · previous app. Source: lab/log.md, H1b.
Reports with an invented number
Reports with an invented number. Before 28 of 90, After 6 of 90. Lower is better.
Number check plus one repair call, p = 0.031 · previous app. Source: lab/log.md, E11.
Judge wrong keeps
Judge wrong keeps. Before 19 of 72, After 4 of 72. Lower is better.
With a plain text check, in-sample · previous app. Source: README, Checking the judge.